A cheaper AI plan is not a bargain if you spend half an hour correcting every result. A more expensive tool is not automatically wasteful if it reliably finishes a job that used to take you two hours. The useful number is not how often you open the app. It is how much finished, usable work comes out the other side.
On July 17, OpenAI published a proposed scorecard for AI spending built around what it calls useful intelligence per dollar. The company argues that businesses should look beyond licenses, active users, and token prices. Instead, they should measure completed work, the full cost of a successful task, the dependability of the result, and whether value grows as usage expands.
This is OpenAI’s own framework, not an independent accounting standard. It also supports the company’s case for using more capable models when they reduce retries and review time. Still, the central idea is useful for a one-person business: judge an AI tool by the work it helps you finish, not by how impressive it feels during a demo.
What OpenAI is asking businesses to measure
OpenAI’s scorecard begins with one workflow and a clear definition of done. A customer-service task might count only when an issue is resolved. A writing task might count only when a draft is accurate, on brand, and ready to publish. A bookkeeping task might count only when the numbers have been checked and entered in the right place.
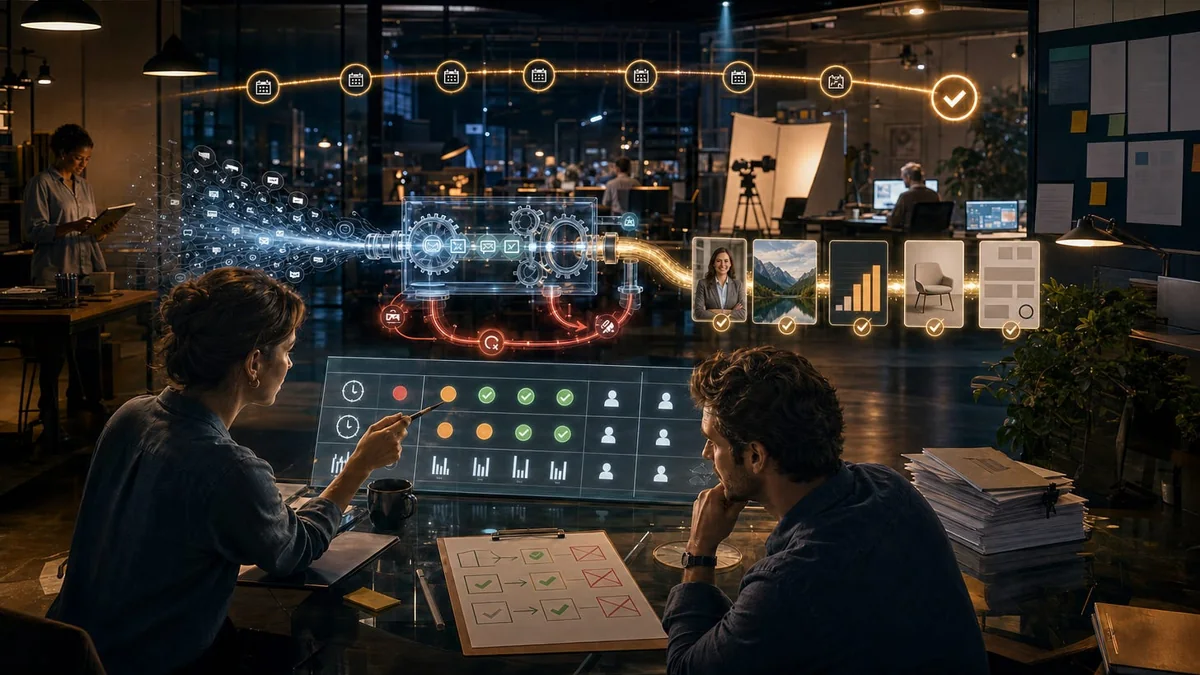
The company says the full cost should include more than the model or subscription price. Employee time, human review, retries, and rework belong in the calculation. It also recommends sorting results into three practical buckets: ready to use, needs correction, and needs escalation to a person.
That last part matters. A tool can appear fast while pushing invisible work onto you. If an AI-written email takes two minutes to generate but fifteen minutes to fact-check and rewrite, the task did not take two minutes. Your review time is part of the cost.
Why this matters to a small business
Most solo creators do not need a finance dashboard for AI. They do need a way to answer ordinary spending questions: Is the paid plan worth keeping? Should I use the fast model or the careful one? Is this automation freeing time, or am I babysitting it?
Usage alone cannot answer those questions. You can use a chatbot every day and still get little finished work from it. You can also use a specialized tool twice a month and save enough time on invoicing, video captions, product descriptions, or research to justify the cost.
Accuracy and oversight have to stay in the picture. The NIST AI Risk Management Framework calls for defined human roles, regular measurement, testing before and during use, and documentation of errors and impacts. NIST’s March 2026 report on deployed AI systems also notes that monitoring remains difficult, especially when human feedback loops and performance drift are involved. In plain language: a workflow that worked last month still needs spot checks.
Run a seven-day AI value test
Pick one repeated task. Do not test your entire business at once. Choose something you will do at least three times this week, such as drafting customer replies, turning notes into social posts, summarizing meeting transcripts, or creating first-pass product descriptions.
Define done before you start. Write one sentence describing a usable result. For a customer reply, that might mean accurate, polite, complete, and ready to send after a quick check.
Record your normal baseline. Time one or two versions of the task without AI, or use a recent example you remember clearly. Include the final review, not just the first draft.
Track every AI attempt. Note the tool or model, total minutes, number of retries, and whether the result was ready to use, needed correction, or needed you to take over.
Count the hidden costs. Include prompt setup, file cleanup, fact-checking, formatting repairs, and time spent moving information between apps.
Review the week, not the best example. Add up completed tasks and total time. One perfect result does not erase four frustrating ones.
A simple scorecard you can keep in Notes
You can track the test with six fields: task, tool, total minutes, retries, result status, and a short note about what went wrong. At the end of the week, compare the AI-assisted average with your baseline.
Keep the tool if it consistently reduces total time while meeting your quality bar. Change the prompt, model, or workflow if correction time is eating the savings. Cancel or downgrade it if the work is not frequent enough to justify the price. For sensitive or high-stakes tasks, reliability and human review may matter more than speed.
Do not turn the scorecard into another project. A rough note is enough to reveal whether you are getting finished work or collecting AI subscriptions.
What to watch next
Watch for AI vendors to add more outcome reporting inside business products. Useful dashboards would show completion rates, retries, correction patterns, and human handoffs without pretending that every task has the same value. It will also matter whether customers can define their own quality bar instead of accepting a vendor’s success metric.
OpenAI’s scorecard is a proposal, and the company has not announced a universal customer dashboard or standard reporting format with it. The harder work is still local: deciding what counts as done, checking important outputs, and noticing when a once-reliable workflow starts slipping.
The practical takeaway
Choose one task this week and measure the whole job from start to approved result. Count retries and correction time. After seven days, you should be able to say whether the AI tool saved time, improved the work, or simply moved the effort into review and cleanup.
That answer is more useful than a usage streak, a benchmark score, or another impressive demo.
If your seven-day test is a work email, the free Professional Email Composer sample gives you a consistent starting prompt for each attempt. Your scorecard should still count edits and review time.
Sources
OpenAI - A scorecard for the AI age
NIST AI Resource Center - AI Risk Management Framework Core
NIST - New Report: Challenges to the Monitoring of Deployed AI Systems